Better Ways to Transcribe Short Dramas When Voices Overlap and Background Noise Takes Over
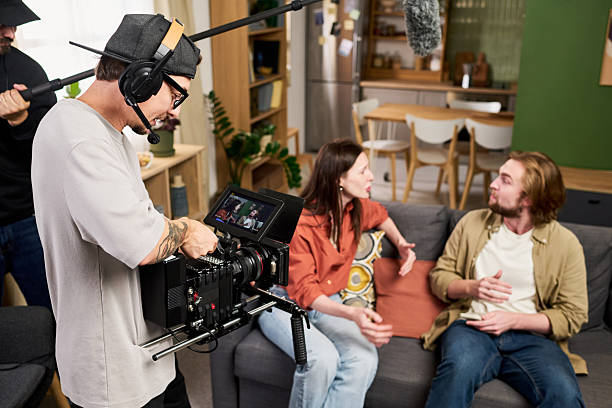
Short-form vertical dramas move fast. A 60-second episode can pack three argumentative exchanges, a sudden confession, and a tense silence filled with traffic or café chatter. The audio rarely arrives clean. Background music swells at the worst moments. Two characters talk over each other. Someone mutters in a regional accent while another raises their voice. For localization teams trying to extract accurate dialogue, generate time-coded scripts, or prepare material for dubbing and subtitling, these conditions routinely break standard automatic speech recognition.
The problems show up in predictable places. Overlapping speech remains the single largest source of error in speaker diarization systems. Most pipelines still assume one voice is active at a time; when two voices sum into the same waveform, the model either drops one speaker, blends both into nonsense, or assigns the wrong label. Research from pyannoteAI and AssemblyAI consistently ranks overlap as the hardest case, especially in the rapid turn-taking common to short dramas. Background noise and far-field recording compound it. Environmental sounds, BGM, and low signal-to-noise ratios push word error rates higher and scramble speaker boundaries. Accents and dialectal variation add another layer—models trained primarily on standard varieties of a language lose accuracy on regional speech that appears frequently in Southeast Asian and other regional productions.
Manual cleanup then becomes the bottleneck. Aligning timestamps by hand across dozens of short episodes drains time that could go into cultural adaptation or quality review. Teams working on Thai or Indonesian short dramas feel this pressure acutely. Those markets have grown quickly; Southeast Asia accounts for a large share of global viewing hours in the format, with strong demand for both subtitled and dubbed versions. Inaccurate base transcripts slow everything downstream.
Practical techniques that actually improve results start with the audio itself rather than the transcription model. Source separation tools that isolate vocals from music and effects—approaches built around models such as Demucs or dedicated dialogue extractors—give the ASR engine a cleaner signal. The separation is rarely perfect, and light residual music is often preferable to aggressive processing that introduces artifacts. Once the voice stem is isolated, a strong diarization model that explicitly handles overlap (modern systems now detect simultaneous speech and can attribute two active speakers) produces more usable speaker-attributed segments. Forced alignment tools then refine the timestamps so that the resulting script lines up tightly with the picture.
For high-noise material, a hybrid pipeline works better than pure end-to-end automation. Pre-process with noise-aware enhancement and vocal isolation, run multi-speaker ASR with diarization, then apply human review focused only on the high-error regions—overlaps, rapid dialectal exchanges, and low-energy lines. This reduces the volume of manual timeline work without pretending that current models solve every case. Language-specific fine-tuning or models that have seen substantial data in Thai, Indonesian, and related varieties further cuts error rates on accented or dialect-heavy dialogue.
The same pipeline supports script auto-generation for localization. Once a reliable, time-coded transcript exists, teams can adapt it for cultural fit, generate subtitle files optimized for vertical screens, or feed it into dubbing workflows. High-precision human-in-the-loop dictation remains essential for final delivery when legal, creative, or brand accuracy matters; pure automated output still requires checking for the subtle meaning shifts that noise and overlap introduce.
These challenges are not unique to any single market. Production teams in Europe, Latin America, and North America face the same noisy, multi-speaker source material when localizing short-form content or preparing it for global platforms. What changes is the language mix and the cultural expectations around emotional delivery and pacing. Solutions that combine robust separation, overlap-aware diarization, and targeted human review scale across languages far more effectively than language-agnostic tools applied without adaptation.
Artlangs Translation has built deep practical experience in exactly these workflows. With more than 20 years focused on translation services, video localization, short-drama subtitle localization, game localization, multilingual dubbing for short dramas and audiobooks, and multilingual data annotation and transcription, the company works across 230+ languages and draws on a network of over 20,000 professional linguists. That combination of technical process and language coverage has supported numerous high-volume short-drama and multimedia projects where noisy, multi-speaker source audio is the norm rather than the exception. The result is transcripts and localized assets that hold up under the real conditions of fast-turnaround global content.